
Training time limited the experiment
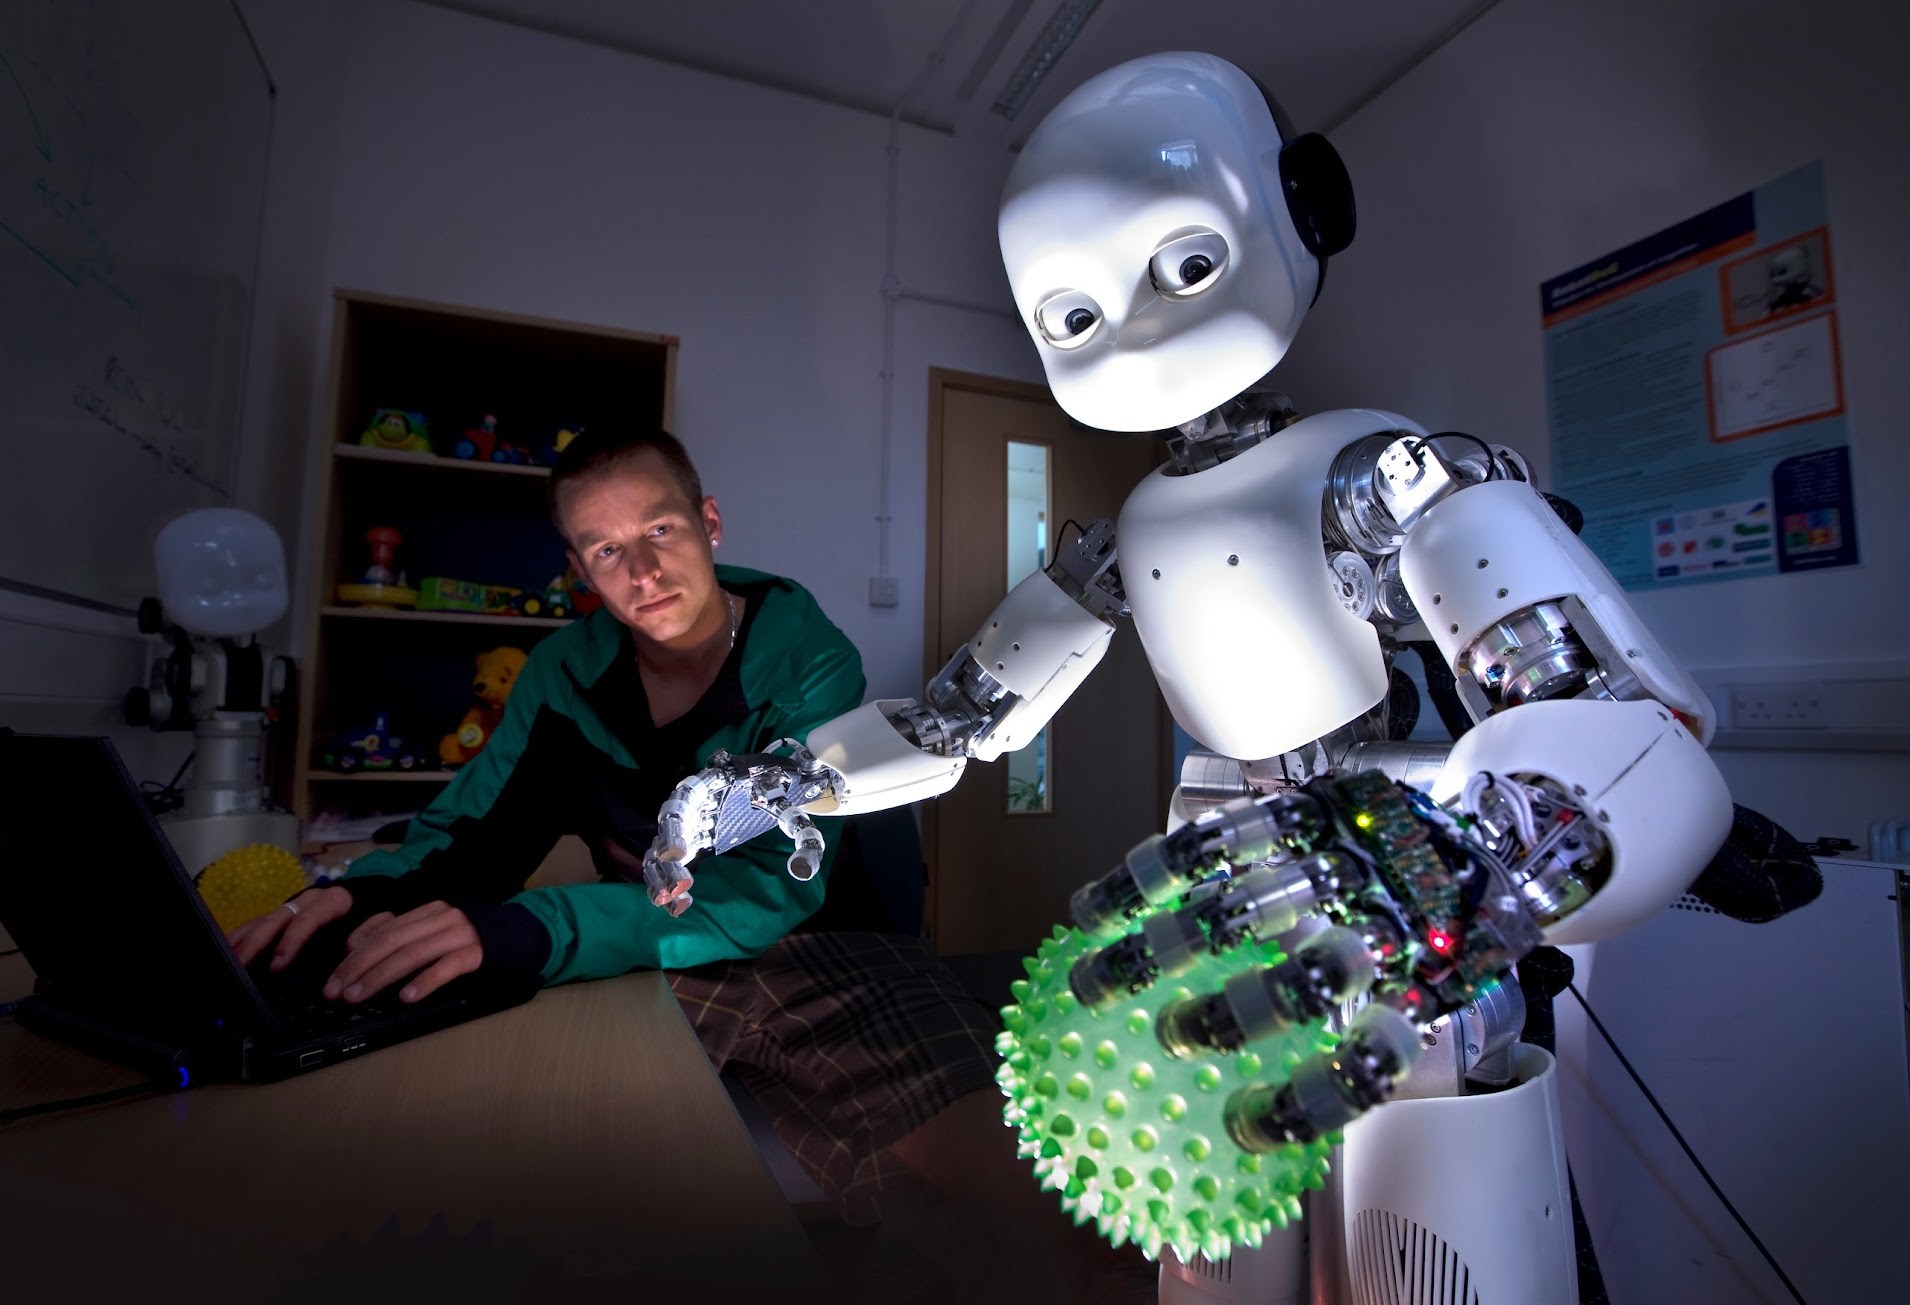
Learning an action means learning a sequence, not recognising one photograph. Larger neural models could connect more sensory information, movements and words, but their training cost constrained what researchers could try. A GPU runs many calculations in parallel; the question was how to use that capacity for embodied learning.


